---
title: Overview
bibliography: ../../references.bib
filters:
  - diagram
diagram:
  engine:
    tikz:
      execpath: lualatex
      header-includes:
        - '\usetikzlibrary{automata, positioning, arrows, decorations.pathreplacing, fit, backgrounds, calc, shapes.multipart}'
---

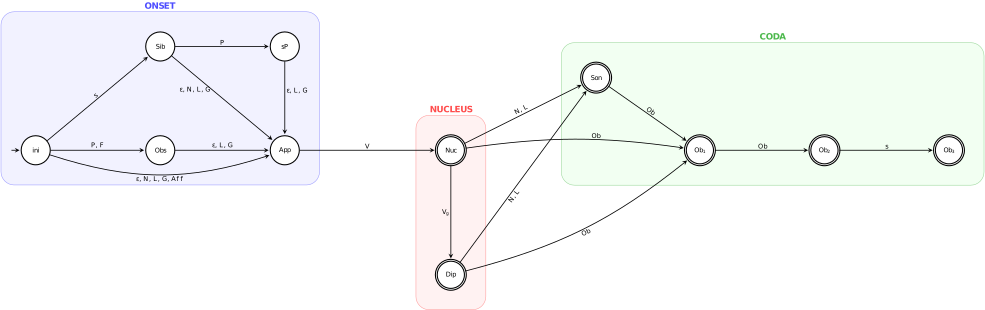
What does an FSA look like when it describes a phonological pattern? We'll start with a small application to English syllable structure. English allows up to three consonants in an onset and several consonants in a coda, but the possible clusters are heavily constrained. The machine below is a **toy syllable automaton**: it records a few broad ordering generalizations, not the complete English inventory.

The broad natural-class labels make the machine readable, but they also make it overgenerate. For instance, an edge labeled $P$ followed by one labeled $L$ admits every stop-liquid combination, including combinations English excludes. A full grammar would replace these class labels with the individual transitions that the language actually licenses.

Each state is labeled with its role in the toy syllable structure: `Sib` tracks the special behavior of /s/ in onsets, `Obs` tracks obstruents that can start clusters, `App` is the pre-nucleus position where approximants and other singleton-only consonants land, and so on.

```tikz
%%| filename=english-syllables
\begin{tikzpicture}[
    > = stealth,
    shorten > = 1pt,
    semithick,
    every state/.style = {draw=black, thick, fill=white, minimum size=14mm, font=\small},
    lbl/.style = {font=\small, inner sep=2pt},
    scale=0.55, transform shape
]

% ONSET STATES
\node[state, initial, initial text=] (ini) at (0, 0) {\textsf{ini}};
\node[state] (sib) at (6, 5) {\textsf{Sib}};
\node[state] (obs) at (6, 0) {\textsf{Obs}};
\node[state] (sP) at (12, 5) {\textsf{sP}};
\node[state] (app) at (12, 0) {\textsf{App}};

% NUCLEUS STATES
\node[state, accepting] (nuc) at (20, 0) {\textsf{Nuc}};
\node[state, accepting] (dip) at (20, -6) {\textsf{Dip}};

% CODA STATES
\node[state, accepting] (son) at (27, 3.5) {\textsf{Son}};
\node[state, accepting] (ob1) at (32, 0) {\textsf{Ob\textsubscript{1}}};
\node[state, accepting] (ob2) at (38, 0) {\textsf{Ob\textsubscript{2}}};
\node[state, accepting] (ob3) at (44, 0) {\textsf{Ob\textsubscript{3}}};

% === ONSET TRANSITIONS ===

% ini -> Sib: /s/
\path[->] (ini) edge node[lbl, above, sloped] {$s$} (sib);

% ini -> Obs: stops, fricatives
\path[->] (ini) edge node[lbl, above] {$P,\, F$} (obs);

% ini -> App: singleton-only onsets (nasals, liquids, glides, affricates) + null onset
\path[->] (ini) edge[bend right=18] node[lbl, below] {$\varepsilon,\, N,\, L,\, G,\, Aff$} (app);

% Sib -> sP: /s/ + stop
\path[->] (sib) edge node[lbl, above] {$P$} (sP);

% Sib -> App: /s/ + sonorant (sn, sl, sw) or /s/ alone
\path[->] (sib) edge node[lbl, left, pos=0.4] {$\varepsilon,\, N,\, L,\, G$} (app);

% Obs -> App: obstruent + approximant (bl, fr, tw, etc.) or singleton
\path[->] (obs) edge node[lbl, above] {$\varepsilon,\, L,\, G$} (app);

% sP -> App: s+stop+approx (spl, str, skw) or s+stop alone
\path[->] (sP) edge node[lbl, right, pos=0.4] {$\varepsilon,\, L,\, G$} (app);

% === ONSET -> NUCLEUS ===

% App -> Nuc: the only V-labeled edge (all onset paths converge here)
\path[->] (app) edge node[lbl, above] {$V$} (nuc);

% === NUCLEUS TRANSITIONS ===

% Nuc -> Dip: diphthong offglide
\path[->] (nuc) edge node[lbl, left] {$V_g$} (dip);

% === CODA TRANSITIONS (from Nuc) ===

% Nuc -> Son: sonorant coda
\path[->] (nuc) edge node[lbl, above, sloped] {$N,\, L$} (son);

% Nuc -> Ob1: obstruent coda
\path[->] (nuc) edge[bend left=8] node[lbl, above, pos=0.6] {$Ob$} (ob1);

% === CODA TRANSITIONS (from Dip) ===

% Dip -> Son: sonorant coda after diphthong
\path[->] (dip) edge node[lbl, below, sloped, pos=0.4] {$N,\, L$} (son);

% Dip -> Ob1: obstruent coda after diphthong
\path[->] (dip) edge[bend right=12] node[lbl, below, sloped, pos=0.5] {$Ob$} (ob1);

% === CODA CHAIN ===

% Son -> Ob1: sonorant + obstruent (nd, lt, mp, ...)
\path[->] (son) edge node[lbl, above, sloped] {$Ob$} (ob1);

% Ob1 -> Ob2: two obstruents in coda (ks, pt, ft, ...)
\path[->] (ob1) edge node[lbl, above] {$Ob$} (ob2);

% Ob2 -> Ob3: complex coda ending in /s/ (ksts, mpts, ...)
\path[->] (ob2) edge node[lbl, above] {$s$} (ob3);

% === BACKGROUND REGIONS ===
\begin{pgfonlayer}{background}
    \node[fit=(ini)(sib)(sP)(app)(obs),
          draw=blue!40, fill=blue!5, rounded corners=10pt, inner sep=15pt,
          label={[font=\bfseries\large, blue!70]above:\textsf{ONSET}}] {};
    \node[fit=(nuc)(dip),
          draw=red!40, fill=red!5, rounded corners=10pt, inner sep=15pt,
          label={[font=\bfseries\large, red!70]above:\textsf{NUCLEUS}}] {};
    \node[fit=(son)(ob1)(ob2)(ob3),
          draw=green!60!black!40, fill=green!5, rounded corners=10pt, inner sep=15pt,
          label={[font=\bfseries\large, green!60!black!70]above:\textsf{CODA}}] {};
\end{pgfonlayer}

\end{tikzpicture}
```

The state labels reflect where you are in the syllable structure:

| State | Meaning |
|-------|---------|
| **ini** | Initial state; beginning of syllable |
| **Sib** | Onset: /s/ consumed (the sibilant that begins three-consonant onsets) |
| **Obs** | Onset: a stop or fricative consumed |
| **sP** | Onset: /s/ + stop consumed (as in *sp*, *st*, *sk*) |
| **App** | Onset complete; approximant or other final onset consonant consumed; ready for vowel |
| **Nuc** | Nucleus: vowel produced (accepting) |
| **Dip** | Nucleus: diphthong offglide produced (accepting) |
| **Son** | Coda: sonorant (nasal or liquid) consumed (accepting) |
| **Ob₁** | Coda: first obstruent consumed (accepting) |
| **Ob₂** | Coda: second obstruent consumed (accepting) |
| **Ob₃** | Coda: final /s/ consumed (accepting) |

Now consider the notation. The labels on the transitions—$P$, $F$, $N$, etc.—are not individual symbols but *natural classes*: shorthand for sets of phonemes. An edge labeled $P$ actually represents six separate transitions, one for each stop consonant. Similarly, an edge labeled $\varepsilon$ is an [*epsilon transition*](https://en.wikipedia.org/wiki/Nondeterministic_finite_automaton#NFA_with_%CE%B5-moves): it allows the automaton to move between states without consuming any symbol from the input. For instance, the $\varepsilon$ on the edge from **Obs** to **App** lets the automaton treat a single obstruent as a complete onset (skipping the approximant position).

The following table defines each natural class:

| Label | IPA members | Description |
|-------|-------------|-------------|
| $s$ | {s} | The sibilant /s/, which has a special role in English onsets |
| $P$ | {p, b, t, d, k, g} | Stops (plosives) |
| $F$ | {f, v, θ, ð, ʃ, ʒ, h} | Fricatives other than /s/ |
| $Aff$ | {tʃ, dʒ} | Affricates |
| $N$ | {m, n, ŋ} | Nasals |
| $L$ | {l, r} | Liquids |
| $G$ | {w, j} | Glides |
| $V$ | {i, ɪ, e, ɛ, æ, ɑ, ɔ, o, ʊ, u, ʌ, ə} | Vowels (monophthongs) |
| $V_g$ | {ɪ, ʊ} | Offglide vowels (for diphthongs like /aɪ/, /aʊ/) |
| $Ob$ | {p, b, t, d, k, g, f, v, θ, ð, s, z, ʃ, ʒ} | Obstruents (stops and fricatives, in coda clusters) |

To trace through some examples, the word *string* /stɹɪŋ/ follows **ini** $\xrightarrow{s}$ **Sib** $\xrightarrow{P}$ **sP** $\xrightarrow{L}$ **App** $\xrightarrow{V}$ **Nuc** $\xrightarrow{N}$ **Son**. The word *a* /ə/ follows **ini** $\xrightarrow{\varepsilon}$ **App** $\xrightarrow{V}$ **Nuc**. And *cats* /kæts/ follows **ini** $\xrightarrow{P}$ **Obs** $\xrightarrow{\varepsilon}$ **App** $\xrightarrow{V}$ **Nuc** $\xrightarrow{Ob}$ **Ob₁** $\xrightarrow{Ob}$ **Ob₂**.

There are a few components to notice here:

1. The circles represent the *states* of the finite *state* automaton. As you might expect, there are a finite number of them.
2. The arrows represent the *transitions* between states.
3. The labels on the arrows are the *labels* of the transitions, which always come from some alphabet $\Sigma$ (just like in regular expressions).
4. There are two kinds of special states:
   - The *initial state*, which is the one that the automaton starts in.
   - The *final states*, which are the ones that the automaton can (but need not) end in.

The way we can tell whether an FSA generates a string is by starting at the initial state and following the transitions, choosing one symbol on each transition and collecting them to form a string. We're allowed to (but need not) stop when we hit a final state. As long as we stop in a final state, the string we've built is generated by the automaton.